For years, Large Language Models (LLMs) have followed a single, undisputed blueprint: generating text one token at a time, from left to right. While this autoregressive approach has produced stunning results, it comes with a major bottleneck—memory bandwidth. Every single token generated requires loading the entire model's weights into GPU memory, limiting speed and scaling.
Enter DiffusionGemma. Released by Google DeepMind in June 2026, this experimental open-weights model breaks free from the autoregressive mold. Built on the Gemma 4 architecture, DiffusionGemma introduces discrete text diffusion to generate and refine large blocks of text simultaneously.
In this post, we'll dive deep into how DiffusionGemma works, its architectural innovations, speed benchmarks, and how it compares to traditional LLMs.
---
How Discrete Text Diffusion Works
In a traditional LLM, the model predicts the very next word based on all the words that came before it. If you want a 100-word response, the model must run 100 sequential inference steps.
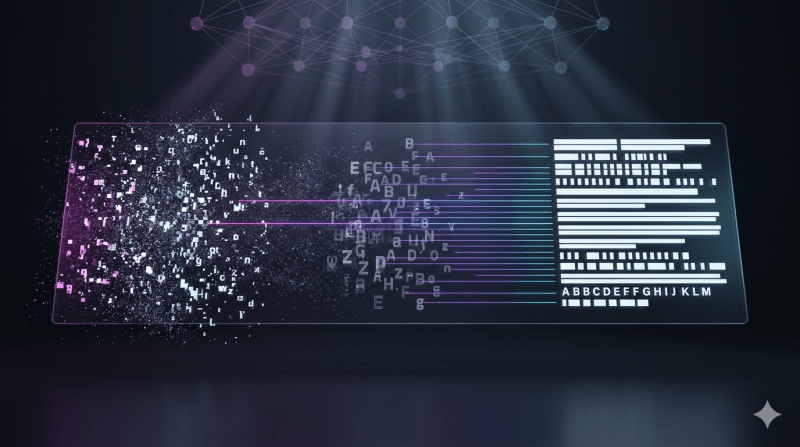
DiffusionGemma operates like an image generation model (like Imagen or Stable Diffusion) but for text:
1. The Canvas: It starts with a blank "canvas" or a sequence of placeholder tokens (up to 256 tokens).
2. Denoising: It iteratively replaces noise (random tokens) with actual words.
3. Bidirectional Context: Instead of only looking to the left, the model looks at the entire canvas—both left and right—to refine the text over multiple denoising steps.
By generating the entire 256-token block in parallel, the model shifts the bottleneck from memory bandwidth (loading weights repeatedly) to compute (processing calculations in parallel), unlocking massive performance gains.
---
Architecture: Under the Hood of DiffusionGemma
DiffusionGemma is built on the Gemma 4 26B Mixture-of-Experts (MoE) architecture, but with a unique encoder-decoder split:
- Autoregressive Encoder: Processes the prompt context (which can include text, images, and videos) in a standard autoregressive manner.
- Diffusion Decoder: Employs bidirectional attention over the generation canvas to iteratively denoise and build the output.
- Active Parameters: Despite having 26B total parameters, only 3.8B active parameters are used per token, allowing the model to run efficiently on consumer-grade hardware with as little as 18GB of VRAM.
---
Speed and Efficiency Benchmarks
The primary advantage of discrete text diffusion is speed. Since the model processes tokens in parallel rather than sequentially:
- 4x Faster Inference: In low-latency, small-batch scenarios, DiffusionGemma can generate text up to four times faster than standard autoregressive models.
- Hardware Friendly: It is optimized for local execution on standard consumer GPUs, making real-time interactive AI assistant applications highly responsive.
---
The Trade-offs: Speed vs. Accuracy
While DiffusionGemma is incredibly fast, it is still an experimental model with notable trade-offs:
| Feature | Autoregressive (Standard Gemma 4) | Discrete Diffusion (DiffusionGemma) |
| :--- | :--- | :--- |
| Generation Style | One token at a time | Entire blocks in parallel |
| Factual Accuracy | High (validates against prior context) | Medium (potential for inconsistency) |
| Inference Bottleneck | Memory Bandwidth | Compute Power |
| Use Case | Production-grade reasoning, long essays | Real-time editing, low-latency tasks |
Because the model generates text in parallel blocks, it sometimes lacks the tight contextual coherence of autoregressive models, which can lead to minor factual errors or repetitive phrasing. Therefore, it is best suited for interactive drafting, editing, and rapid prototyping rather than critical factual lookups.
---
Final Thoughts
DiffusionGemma marks a fascinating milestone in DeepMind's open science contributions. It proves that discrete text diffusion is not just a theoretical concept but a viable path toward super-fast, compute-bound local AI generation. As developers and researchers experiment with this new architecture, we can expect hybrid systems that combine the speed of diffusion with the reasoning capabilities of autoregressive models.
---
FAQs
What is DiffusionGemma?
DiffusionGemma is an experimental, open-weights multimodal model by Google DeepMind that uses discrete text diffusion instead of autoregressive token generation to produce text.
How does text diffusion differ from standard text generation?
Standard generation predicts one word at a time, sequentially. Text diffusion starts with a noisy canvas of tokens and refines the entire block of text simultaneously over multiple steps.
What are the main benefits of DiffusionGemma?
The primary benefits are speed (up to 4x faster local inference) and parallel block generation, which changes the hardware bottleneck from memory bandwidth to GPU compute.
What inputs does DiffusionGemma support?
It is a native multimodal model, meaning it accepts text, images (with variable aspect ratio support), and video inputs to generate text.
Can I run DiffusionGemma locally?
Yes. Thanks to its Mixture-of-Experts (MoE) architecture, it has only 3.8B active parameters, making it fit within 18GB of VRAM on consumer-grade GPUs.